Now, whether or not we have a complete matching, we would still like to try to find a maximum matching in our graph. One way to do this is greedily: just choose edges until we get a maximal matching. Such a matching might not be maximum, so we would like a way to figure out if, when we find ourselves with a maximal matching, whether there’s a way to get a better matching or if such a matching exists. We will make use of the following idea.
Let $G$ be a graph with a matching $M$.
Let’s have a look at what an augmenting path looks like.
Consider again our example with $M = \{(1,8), (2,6), (3,7)\}$. One possible augmenting path is: $0, 6, 2, 8, 1, 5$.
Note that in order for a path to be augmenting, both endpoints of the path must be unmatched. It is not enough that only one endpoint is unmatched.
Now, if we take the path and swap the edges in and out of $M$, we get the matching $M' = \{(0,6), (1,5), (2,8), (3,7)\}$.
Notice that there are no augmenting paths with respect to $M'$, so it is a maximum matching.
Let $G = (V,E)$ be a graph with a matching $M$. If $G$ has an $M$-augmenting path, then $M$ is not a maximum matching.
First, we note that an $M$-augmenting path must be odd. Otherwise, the edges on the end can’t both be outside of the matching. So suppose $G$ contains an $M$-augmenting path $P$, denoted as a sequence of edges $P = e_1 e_2 \cdots e_{2k+1}$. By definition, $e_2, e_4, \dots, e_{2k} \in M$ and $e_1, e_3, \dots e_{2k+1} \not \in M$.
We define the matching \[M' = M \triangle P = (M \setminus \{e_{2i} \mid 1 \leq i \leq k\}) \cup \{e_{2i+1} \mid 0 \leq i \leq k\}.\]
So $M'$ is a matching of $G$ that is constructed by removing $k$ edges from $M$ that were on our path and adding the other $k+1$ edges on our path. Thus, $|M'| = |M| + 1 \gt |M|$. So $M$ was not a maximum matching.
Here, $\triangle$ denotes the symmetric difference of two sets. For two sets $A$ and $B$, \[A \triangle B = (A \cup B) \setminus (A \cap B).\] In other words, the symmetric difference is the set theoretic analogue of “exclusive or”—the set of those things that belong to $A$ or $B$ but not both.
This lemma about augmeting paths turns out to be one direction for Berge’s lemma, due to Claude Berge in 1957, which says that this condition is necessary and sufficient.
Let $G = (V,E)$ be a graph with a matching $M$. Then $M$ is a maximum matching if and only if there is no $M$-augmenting path.
We get an algorithm from this result:
This is still a bit underspecified for an algorithm, but luckily, that will be something you will see if you take Theory of Algorithms, in the context of max-flow algorithms.
Furthermore, while this is true for any matching, simply applying this method as an algorithm runs into one possible complication. Consider the following graph and matching.
Observe that if we attempt to find our augmenting path by starting from vertex $6$, we could end up getting stuck, depending on whether we move from vertex $4$ to vertex $0$ or vertex $3$.
Now, you might say, hold on, this graph is not bipartite! And that’s true, this is not a bipartite graph. But, if we look carefully at the definition of matchings and the statement of Berge’s lemma, we’ll find that neither of these actually depends on the fact that $G$ is bipartite! Luckily, this issue with our algorithm is only a problem for graphs that are not bipartite. Why? The problem arises when the graph contains and odd cycle and...
A graph $G$ is bipartite if and only if $G$ does not contain a cycle of odd length.
A proof of this is given in the textbook (Theorem 12.8.3), but it is stated in terms of colourability.
So for bipartite graphs, the algorithm that we’ve described works perfectly fine without much complication—no need to worry about odd cycles. But what about for general graphs? It takes a bit more work, but the same idea works once you can figure out how to deal with odd cycles. This result is due to Jack Edmonds in 1965, who gave the first efficient algorithm for computing maximum matchings in general graphs, and which contributed to the idea of “efficient” algorithms as those with polynomial running times.
Now that we have spent some time on learning how to enumerate outcomes, we can start to think about the likelihood of particular outcomes. This is where probability theory comes into play. In particular, we are interested in discrete probability, which deals with countably many outcomes and is attacked using many of the tools that we’ve been using in this class. The “non-discrete” branch of probability theory deals with uncountably many outcomes and is approached using methods from calculus and analysis. For instance, where we can get away with summation, you will see a lot of integration when working with probability distributions that are continuous.
At first glance, even though we’re primarily concerned with discrete probability, it seems a bit strange that we’d try to stuff probability theory into this course which is already chock full of other things to cover. But probability and randomness play an important role in computer science and particularly in theoretical computer science. Probabilistic methods are an important part of analysis of algorithms and algorithm design. There are some problems for which we may not know of an efficient deterministic algorithm, but we can come up with a provably efficient randomized algorithm. To tackle these problems, we need a basic understanding of discrete probability. The nice thing about this is that we don’t really need too much fancy probability theory for this purpose.
A probability space $(\Omega,\Pr)$ is a pair of a finite set $\Omega \neq \emptyset$ together with a function $\Pr : \Omega \to \mathbb R$ such that
We say that $\Omega$ is the sample space and $\Pr$ is the probability distribution.
A sample space for flipping a coin would be whether it lands on heads and tails $\{H,T\}$. A sample space for the outcome of a die roll would be $\{1,2,3,4,5,6\}$. A probability distribution for a fair coin would be $\Pr(H) = \Pr(T) = \frac 1 2$, while a probability distribution for a fair die would be $\Pr(\omega) = \frac 1 6$, for $\omega \in \{1,2,3,4,5,6\}$. On the other hand, a probability distribution for a biased coin may be something like $\Pr(H) = \frac 2 3$ and $\Pr(T) = \frac 1 3$.
The above two conditions are known as the probability axioms and is due to Andrey Kolmogorov in the 1930s. Kolmogorov was a Soviet mathematician and was particularly influential in computer science by developing notions of algorithmic information theory in the 1960s. It might be a bit surprising to learn (as I did) that the formalization of basic probability concepts didn’t come about until the 20th century, despite there being analysis of games of chance dating back to 17th century France.
We can define more set theoretic notions for probability.
An event is a subset $A \subseteq \Omega$ of the sample space.
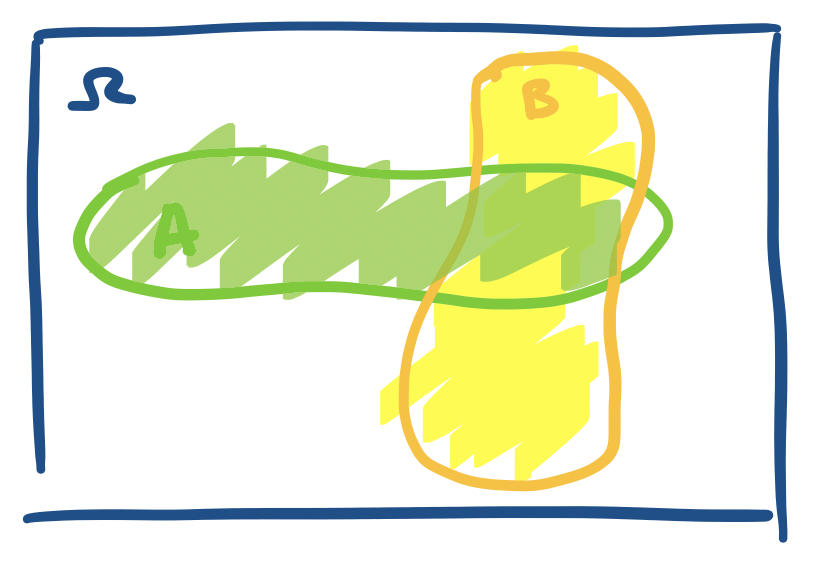
Because the sample space and events are just sets, we can often give “schematic” visual representations of them in the same way as sets. For example, the following is the sample space $\Omega$, which we treat in the same way as a universe, and events $A$ and $B$.
Intuitively, if we “throw a dart” at $\Omega$, then the probability that it lands in $A$ should be the $\Pr(A)$.
An event can be something simple like flipping a coin and it landing on heads, in which case the event would be the set $\{H\}$ and the probability of this event is $\frac 1 2$. It can also be more complicated, like a die roll landing on a square, which would be the set $\{1,4\}$, or perhaps the positive divisors of 6, which would be the set $\{1,2,3,6\}$. Then the probability of these events is $\frac 2 6 = \frac 1 3$, and $\frac 4 6 = \frac 2 3$, respectively.
For each sample space, we define a probability distribution, which tells us the probability of a particular event $\omega \in \Omega$. This can be any function that satisfies the axioms we outlined, but there will be “special” distributions of interest that are commonly used. The simplest one is the uniform distribution.
The uniform distribution over a sample space $\Omega$ defines $\Pr(\omega) = \frac 1 {|\Omega|}$ for all $\omega \in \Omega$. Thus, $\Pr(A) = \frac{|A|}{|\Omega|}$.
Typically, this is the distribution we assume when we have an arbitrary finite set and say pick an element at random from our set—every item has an equal probability of being chosen:$\frac 1 n$ for $n$ elements, or $\frac{1}{|\Omega|}$.
In some sense, our picture of $\Omega$ and events $A$ and $B$ above is a bit inaccurate under our particular definitions, because it depicts a continuous sample space. However, we can still visualize an explicitly discrete sample space by breaking it up into discrete chunks.
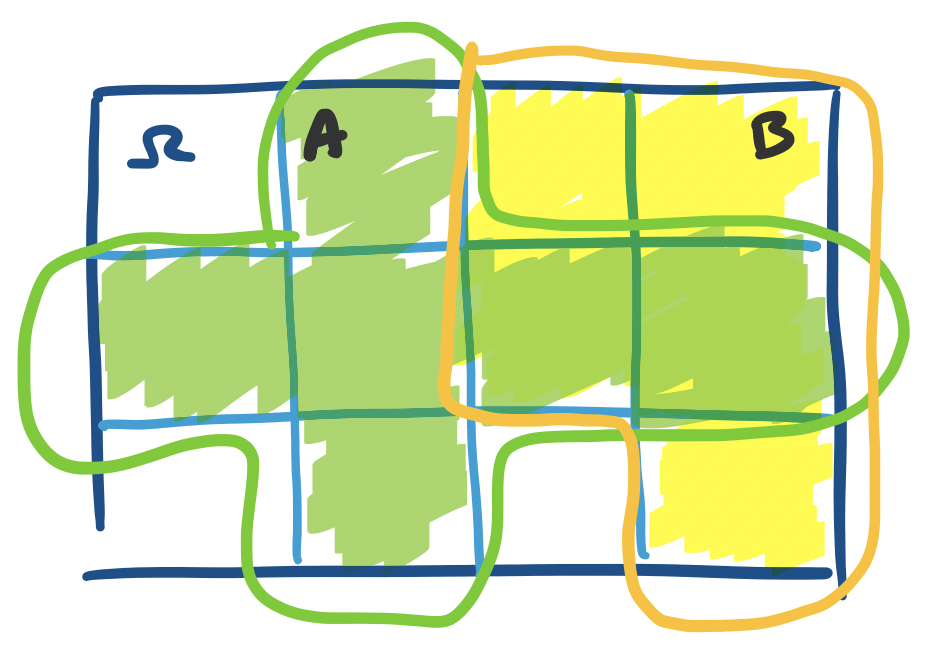
Here, we have the same idea, except we have discretized the space into 12 blocks, each of equal size. This then gives us $\Pr(A) = \frac 6{12} = \frac 1 2$ and $\Pr(B) = \frac{5}{12}$.
To determine the probability of an event (i.e. solve a problem), the textbook outlines a helpful process.
It’s clear from above that the sample space for rolling one die is $\{1,2,3,4,5,6\}$, but what about two dice? Suppose we want to know the probability that our roll of two dice sums to 8.
What about coins? It turns out that flipping a bunch of coins is probably the most important sample space for theoretical computer science. Why? Let’s try to do the same exercise as with dice. What if we want to represent a series of three coin flips? We can play the same game as with the dice: we have $\{H,T\} \times \{H,T\} \times \{H,T\}$ for our sample space. Now, if we were to generalize this to $n$ coin flips, we would have something like $\{H,T\}^n$. This space looks a lot more familiar if we rename $T = 0$ and $H = 1$, giving us the space $\{0,1\}^n$. That’s right—the sample space of $n$ coin flips can be represented as the set of length $n$ binary strings!
Suppose we’d like to know for a series of 12 coin flips what the probability that we have exactly 8 heads is.
The view of a series of coin flips as binary strings is nice because it gives a bit of insight into how we might think of generating a random number. Typically, we think of a random number as something that we just “choose” “at random”, but most people do not make choices that are truly uniformly at random. This suggests a better way of thinking about random numbers. First, figure out how large of a random number you want. Then flip a coin $n$ times, where $n$ is the size of your number. Then you have a binary string that you can interpret as a number!
This also suggests that creating a larger random number requires a “more” randomness and it gives us a way to think about randomness as a resource. If we need more coin flips, we are using more bits of randomness. We can then treat this quantity as a resource just like we do with time or space and ask how much randomness we might need for an algorithm and talk about the amount of randomness as a size of the input to the algorithm.
Recall that a standard deck of playing cards consists of four suits, $\spadesuit, \heartsuit, \clubsuit, \diamondsuit$ with cards numbered from 2 through 10, and a Jack, Queen, King, and Ace. This gives us 52 cards in total ($4 \times 13$). Suppose we want to know when drawing five cards what the probability that we can draw a flush is—that is, five cards of the same suit. (Technically a flush will exclude things like straight flushes, but we’ll ignore that at this point)
Since we are dealing with sets, we can combine our sets in the same way as we’ve been doing to consider the probability of multiple events together. First, the following is a simple, but important bound.
$\Pr(A \cup B) \leq \Pr(A) + \Pr(B)$.
Just like with sets, we can define the notion of disjointness for events.
Events $A$ and $B$ are disjoint if $A \cap B = \emptyset$.
$\Pr \left( \bigcup\limits_{i=1}^k A_i \right) \leq \sum_{i=1}^k \Pr(A_i)$. Furthermore, this is an equality if and only if the $A_i$ are pairwise disjoint.
This is just a generalization of the union bound and the proof comes straight from applying it. Alternatively, you can use induction to prove this. If you consider the events to be disjoint, this is really pretty much the sum rule. As you might have noticed, this result is due to George Boole, who is the same Boole that gave us Boolean algebra. Often times, this is also called the union bound.
There are a number of other useful properties that we can derive from set theory.
Let $A$ and $B$ be events. Then